Your Data Never Leaves Your Network.
Most AI tools ship your customer records, contracts and case files to somebody else's servers, and bill you for every word. We put the AI on a server you own, inside your building, trained on your documents. Our engineers fly out and install it. After that there is no token bill and nothing to send anywhere.
Nothing crosses the line.
Prompts, documents and outputs stay inside the perimeter you approve. Air-gapped if that's what your policy requires.
Book A Private AI Assessment →You're not slow to adopt AI. You're just not allowed to leak data.
Legal teams, clinics, financial firms, defence suppliers, HR departments, anyone operating under NDA: the interest in AI is already there. What stops the project is a data processing agreement nobody will sign, or a client contract that says your files stay on your systems.
A private deployment removes that conversation entirely. The model runs where your data already lives, so there is no third party to vet, no retention policy to argue about, and no vendor that can change the terms underneath you.
Buy the machine once. Stop paying per word.
A hosted API charges you for every request, forever, and the bill grows as your team uses it more. A private deployment is one hardware purchase plus electricity. Move the sliders and see where the two lines cross.
Staff who would run documents, drafting, search or support work through the model.
What you spend now, or what you would spend if every one of those people used a hosted model properly.
Token bills rarely stay flat. As people find more uses, the hosted bill climbs with them. The private cost does not.
Model upgrades, retraining, monitoring and an engineer on site when a new model is worth moving to. Optional, and separate from the build.
A multi-GPU server in one rack. Sized on real concurrency, confirmed during the assessment.
You pay for the hardware once. After that the only bill is electricity and the care plan.
Hardware plus the build. One time.
Power, cooling and care. No token bill.
Everything after this is money you keep.
How to read this. Hardware and build figures are indicative ranges from deployments of this shape, not a quote. Real numbers depend on which models you need, how many people hit them at once, and what already exists in your stack. We give you the exact figure during the assessment, before you buy a single GPU. If the maths does not favour a private deployment for you, we will say so.
From locked down to live in weeks.
No pilot that runs for a year. We scope it against your security policy, prove the quality on your own tasks, and then put it into production.
Our engineers come to you. Nothing dials home.
There is an easy version of this where we install remote access software on your server and work from another country. We do not do that, because it would hand you back the exact risk you are trying to remove. We get on a plane instead.
We fly in and build it on site
Our engineers work in your building, on your network, on the server you own. The model, the fine-tuning and the integrations all happen behind your firewall while your team watches it being done.
No remote access left behind
When we leave, there is no backdoor, no VPN tunnel to us, no agent phoning out. The server can sit fully air gapped if that is what your policy says. Your IT team holds every credential.
Local language, handled locally
Outside English speaking markets we bring in a local language partner for the interface, the documents and the training data. The model reasons in English, which is where these models are strongest, and the output comes back in your team's language.
Then we keep it current. Open models improve every few months. When one is genuinely worth moving to, we test it against your reference set first, take a full backup, and an engineer applies the upgrade on your site. The model itself never gets permission to delete anything. That is the care plan, and it is optional.
The result, and the guarantee.
The result
The work your team repeats every day, drafting, extracting, summarising, classifying, handled by a model that speaks your vocabulary. Sensitive material stays in-house, your cost stops scaling with every request, and the system keeps running if a vendor changes pricing or policy.
The guarantee
We benchmark before you spend anything on hardware. If a private model can't reach the quality bar on your use case, we tell you plainly and point you at the cheaper answer, even when that answer isn't us. We would rather lose a project than sell you a downgrade.
Four pieces. One private stack.
Most companies need two or three of these, not all four. We scope it to the workflow that's actually costing you time.
Private LLM Deployment
An open-weight model installed and served inside your environment, with the API your applications talk to sitting behind your own firewall.
- Sized against your real concurrency, not a guess
- Standard OpenAI-compatible endpoint for easy integration
- Runs air-gapped when policy requires it
- Access control and audit logging you own
Fine-Tuning On Your Domain
Prompting steers a general model. Fine-tuning teaches it your formats, your terminology and your edge cases, so output is consistent instead of nearly right.
- Training set built from your existing documents
- Shorter prompts, lower cost per request
- Consistent structure your systems can parse
- Retrained on a schedule as your business shifts
Private Knowledge Retrieval
Your manuals, contracts, tickets and policies made answerable, with a vector index that lives on your infrastructure alongside the model.
- Answers cite the source document
- Respects your existing permission model
- No documents uploaded to an outside index
- Refuses to answer rather than inventing
Evaluation & Guardrails
A private model without evaluation is a liability. We build the scoring harness that tells you when quality drifts, before your users find out.
- Reference test set built with your experts
- Automatic scoring on every model change
- Redaction and topic boundaries enforced in code
- Human approval steps wherever risk is high
Three ways to keep it private.
Private does not have to mean a server room. It means your data is processed inside a boundary you control, and we'll tell you which of these fits your policy and budget.
On-premise hardware
A GPU server in your own rack or office. Nothing touches the public internet, which is the only option that satisfies a genuinely air-gapped policy.
Your private cloud
The model runs in your own AWS, Azure or GCP account, inside your VPC and under your existing security controls. No capital spend, no new hardware to look after.
Hybrid routing
Sensitive requests go to the local model, everything harmless keeps using a hosted API. The cheapest way to get most of the benefit without moving your whole stack.
Open weights. No lock-in.
Open models used to be a compromise. For the work most businesses actually run, drafting, extraction, classification, search and support, the current open families are close enough to the hosted frontier that your team will not feel downgraded. We benchmark the shortlist on your own tasks and let the scores decide.
The weights sit on your storage. If you stop working with us tomorrow, the system keeps running and you can hand it to any competent engineer. That is the difference between owning a capability and renting one.
The model on its own does nothing. This is the part that pays.
Installing a local model is the straightforward day. The value comes from what we build on top of it and wire into the software your team already uses.
Agents in your systems
The model connected to your case management, hospital system, CRM or ticketing, so it does the work rather than chatting about it.
Skills for your work
Reusable procedures for the tasks your people repeat all day. Built once for your industry, then reused across every department and every site.
Browser and computer use
The flashy features you see on hosted assistants are tools, not magic. We install the same tools locally so your model can drive a browser or an application.
Voice, scans and documents
Local speech models and document extraction, so recordings, handwriting and PDFs become searchable without a single file leaving the building.
You sell the servers. We make them worth buying.
If you already supply infrastructure to hospitals, law firms, banks or government, your clients are asking you about private AI and you need an engineering partner to answer them. That is the arrangement. You keep the hardware relationship and the hardware margin. We do the part that makes the hardware do something.
Your client asks for private AI
They want the capability but their data cannot leave the building. You already have the relationship and the trust, which is the hard part.
You quote the server and the GPUs
We tell you exactly what to specify for their workload. GPUs are the largest line on the invoice, and it is your invoice.
We fly in and build the system
Model selection, fine-tuning on their documents, the agents that plug into their existing software, evaluation and guardrails. On their site, on your hardware.
You own the account, we keep it running
Co-branded or fully white labelled, your choice. Care and retraining are a recurring line you can resell, and every new department is another server you get to quote.
What you get out of it
- A reason for clients to buy far more compute than they do today
- An answer to the private AI question you are already being asked
- An engineering team that has done this, without hiring one
- Recurring care revenue on top of one time hardware
- Your name on the front of it if you want it there
We will install a private model in your own office at no charge, so your sales team has something real to demo instead of a slide. You provide the hardware, we do the build. Fine-tuning and client work are quoted separately.
Worth doing for some companies. Overkill for others.
This is for you if…
- You handle data under NDA, HIPAA, GDPR or client confidentiality
- Legal or security has already blocked a public AI tool
- You have repetitive document, support or analysis work worth automating
- Your API spend is climbing and won't stop
- You want a system that survives a vendor changing its terms
This isn't for you if…
- You're comfortable sending your data to a hosted API
- Your volume is low enough that per-token pricing is simply cheaper
- You need frontier-level reasoning on wide open-ended problems today
- You want it live next week with no evaluation step
- Nobody internally will own the system after handover
Engineers, not resellers.
We're not reselling somebody else's platform with a markup. We build and operate the system, then hand you the keys.
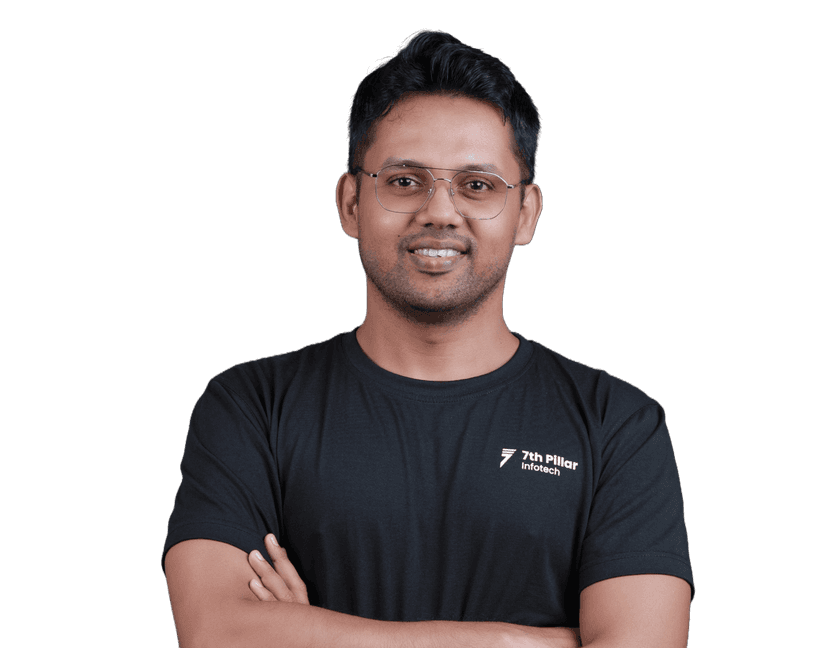
12+ years running 7th Pillar Infotech, building platforms, products and custom AI tooling across industries. Leads model selection, fine-tuning and deployment architecture.
7thpillar.com ↗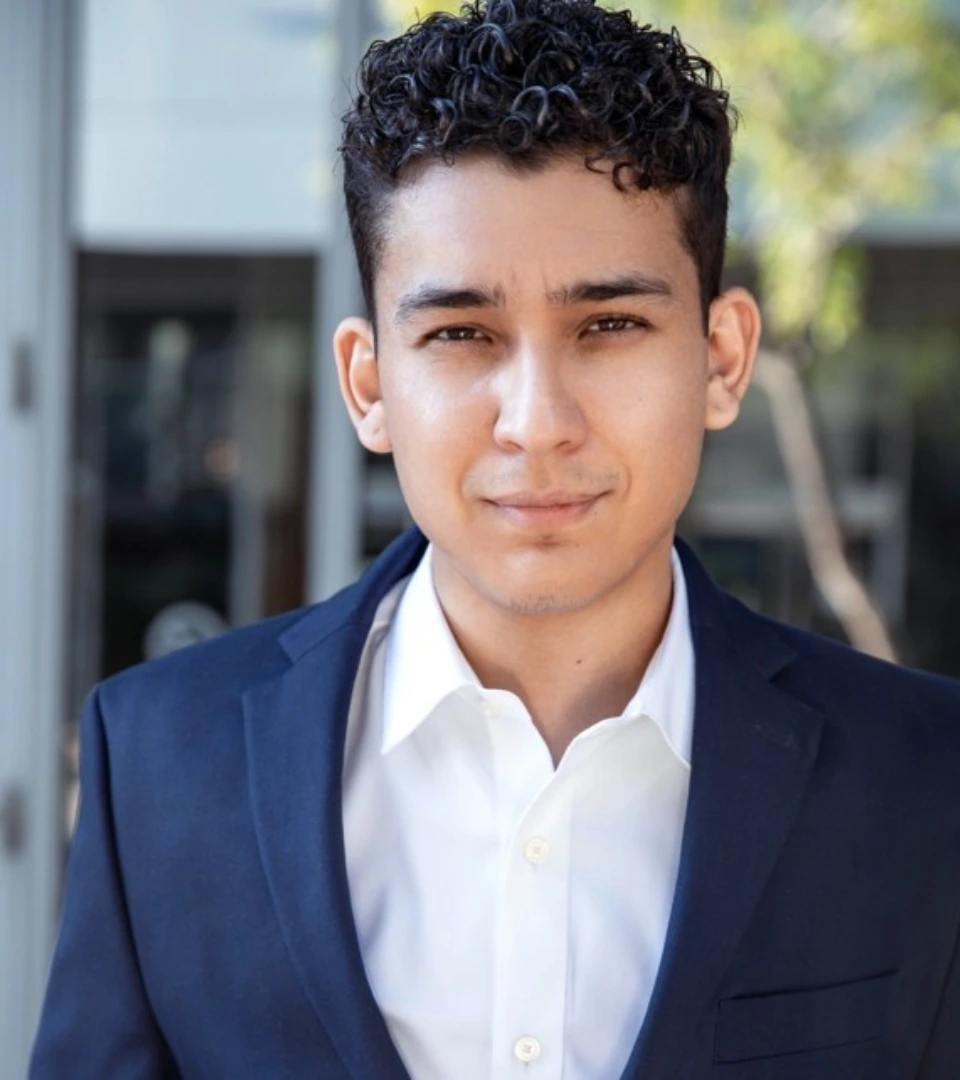
A decade running service businesses in the US. Works out which parts of your operation are actually worth automating, so the build targets real hours instead of a demo.
emmanuelonate.com ↗Before you book
Direct answers. No corporate fluff.
Is an open model actually as good as GPT or Claude?
It depends entirely on the task. On narrow, well-defined work such as extraction, classification, summarising your documents or drafting in your house format, a fine-tuned open model is often just as good and far cheaper to run. On wide open-ended reasoning, the hosted frontier models are still ahead. That is exactly why we benchmark on your tasks before you commit to anything.
What hardware do we need?
It depends on model size and how many people use it at once. Plenty of workloads run comfortably on a single workstation-class GPU. We size it against your real usage during the assessment and give you the number before you buy anything.
Can it run completely offline?
Yes. Once deployed, the model runs locally with no outbound calls at all. Updates and retraining happen on your schedule, applied by you or by us on your network.
Do you train models on our data?
Your data trains your model and nothing else. It never enters a public model, and it never leaves the environment you approve.
Do we still pay per token once it's installed?
No. That is the part people find hard to believe. The model runs on hardware you own, so there is no metered bill from anyone. Your running cost is electricity, cooling, and the care plan if you want one. Whether you send it ten requests a day or ten thousand, the number does not move.
How is fine-tuning different from just writing better prompts?
Prompting steers a general model at runtime. Fine-tuning changes the model itself so it already knows your formats, terminology and edge cases. The practical result is more consistent output, much shorter prompts, and a lower cost per request.
We already use a hosted API. Do we have to rip it out?
No, and usually you shouldn't. A hybrid setup is common: sensitive workloads route to the private model, everything else carries on using the API. You get the compliance win without a rebuild.
Who owns the model when we're done?
You do. The weights, the fine-tuned checkpoints, the training data and the deployment configuration are all yours, sitting on your storage. If you stop working with us, nothing switches off.
How does pricing work?
A fixed-scope build so you know what you're buying, plus your own infrastructure cost. Ongoing care and retraining are optional and separate. There is no per-token bill from us.
How do you install it without remote access to our network?
Our engineers travel to your site and do the work there. We do not install remote access software, because that would reintroduce the exact risk you are paying to remove. When the build is finished there is no tunnel back to us and your IT team holds every credential.
Our staff don't work in English. Does that break it?
No. These models reason best in English, so that is what runs under the hood, and the output comes back in your team's language. Where the interface, the documents or the training data need local expertise we bring in a local language partner alongside our engineers.
What happens when a better model comes out?
We test the new model against the reference set your experts signed off on, and only recommend the move if it actually scores better on your work. Then we take a full backup and an engineer applies it on site. The model is never given permission to delete anything, and nothing changes on your system without your sign-off.
Find out if private AI is worth it for you.
Bring us the workflow and the constraint. We'll tell you which model class can handle it, roughly what hardware it takes, and whether a private deployment beats simply using an API. If it doesn't, you'll hear that too.
Or reach us at hello@rethinkai.now